Sangmin Woo
Applied Scientist @ AWS AI
Contact
-
sangminw [at] amazon.com
shmwoo9395 [at] gmail.com
-
2795 Augustine Dr, Santa Clara, CA 95054, United States
I am an Applied Scientist at AWS Agentic AI. I received my Ph.D. from KAIST.
Humans are inherently multi-modal learners: we naturally interact with and understand the world by seeing (vision), communicating and thinking (language), listening (audio), and acting with agency. I am passionate about advancing machine intelligence to mirror this ability, enabling systems to perceive, reason, and act in the world holistically.
My research interests include, but are not limited to:
- Multi-modal AI: Vision + {Language, Audio, etc.} Multi-modal
- Generative AI (LLMs, VLMs, Diffusion Models, etc.) Gen AI
- Agentic AI (LLM Agents, VLAs, etc.) Agent
- Visual Understanding Video Image
News
- May 20261 paper accepted to TMLR 2026!
- Jan 20262 papers accepted to EACL 2026 (1 Main, 1 Findings)!
- Aug 20251 paper accepted to ESWA!
- Aug 20251 paper accepted to EMNLP 2025 Main!
- Jun 2025I am starting my new chapter at AWS Agentic AI! 🧑🏻💻
- Jun 2025Selected as an Outstanding Reviewer at CVPR 2025!
- May 20251 paper accepted to ACL 2025 Findings!
- May 2025Successfully defended my PhD! 🎓
- Apr 20251 paper accepted to CVIU!
- Feb 20251 paper accepted to CVPR 2025!
- Jan 20251 paper accepted to NAACL 2025 Main!
- Dec 20241 paper accepted to AAAI 2025!
- Sep 2024Excited to keep collaborating with the team remotely!
- Sep 2024I had a fantastic summer internship with AWS Bedrock!
- Jul 20243 papers accepted to ECCV 2024!
- Jun 2024I joined AWS Bedrock as a summer intern!
Publications
* Equal contribution
2026
-
-
-
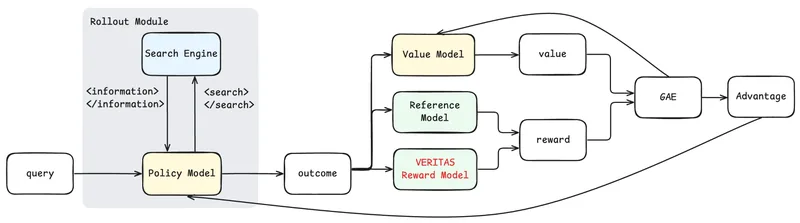
Beyond Correctness: Rewarding Faithful Reasoning in Retrieval-Augmented Generation
TMLR 2026 KnowFM @ ACL 2026
-
-
2025
-
-
-
-
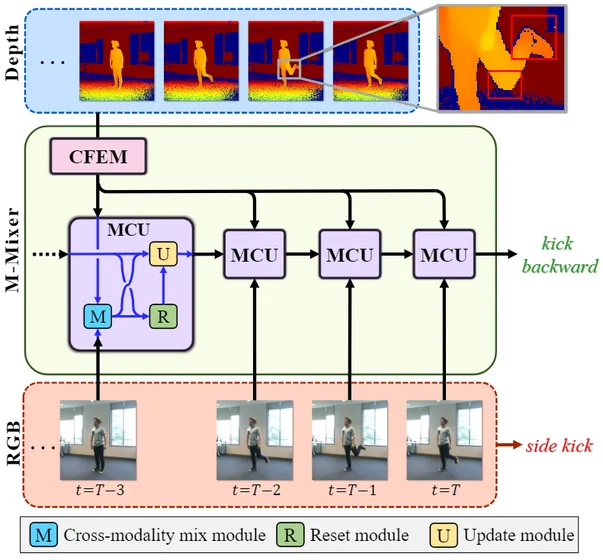
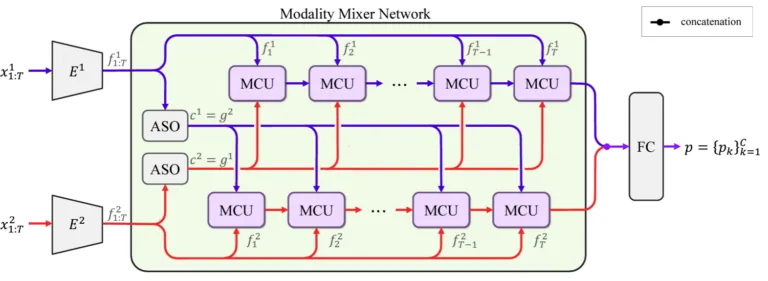
Modality Mixer Exploiting Complementary Information for Multi-modal Action Recognition
CVIU 2025 IF 4.8
-
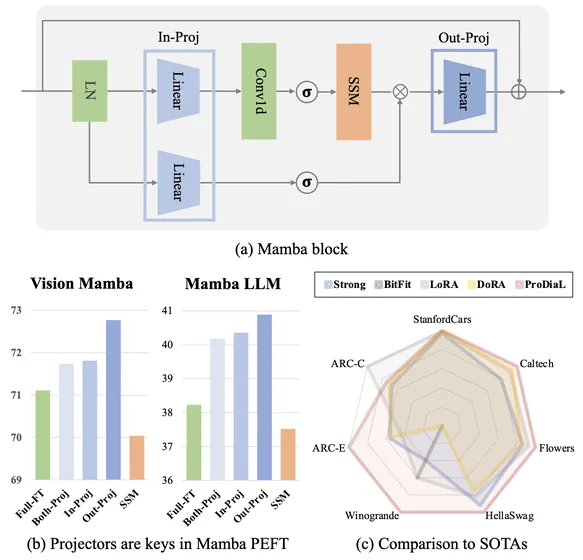
Parameter Efficient Mamba Tuning via Projector-targeted Diagonal-centric Linear Transformation
CVPR 2025
-
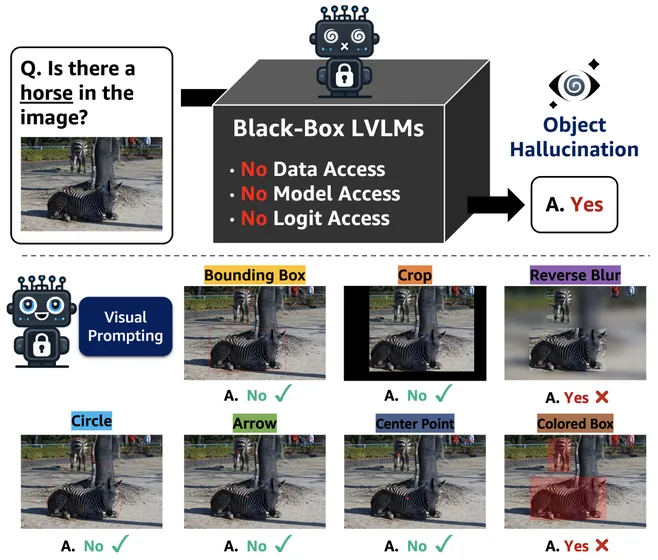
Black-Box Visual Prompt Engineering for Mitigating Object Hallucination in Large Vision Language Models
NAACL 2025
-
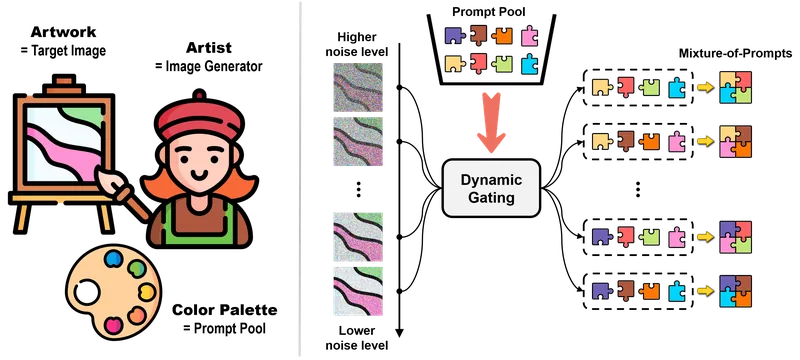
2024
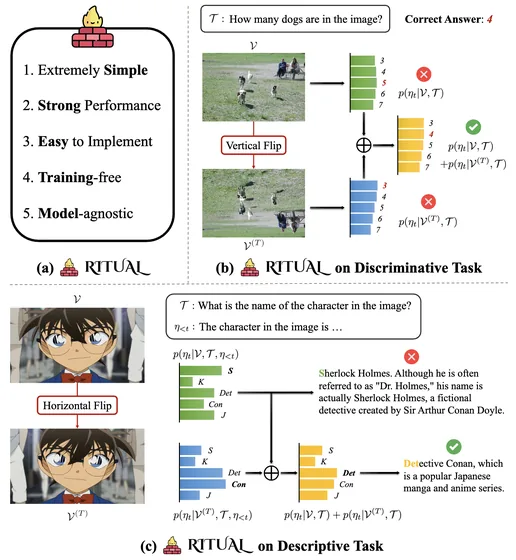
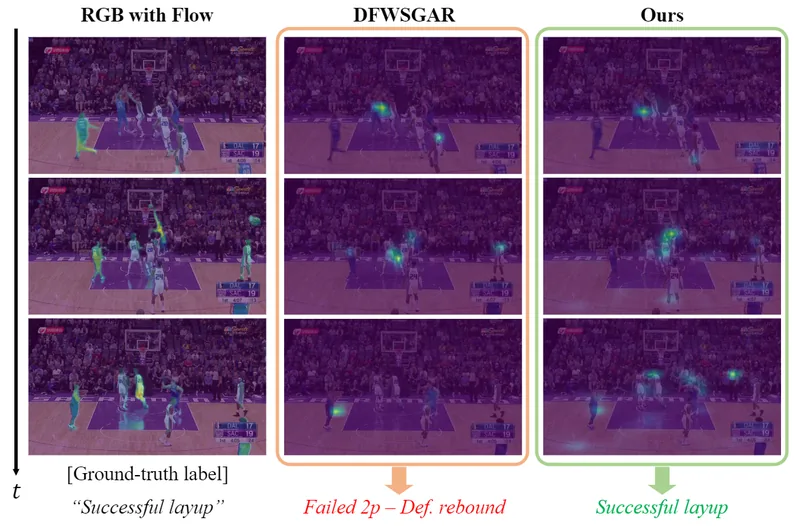
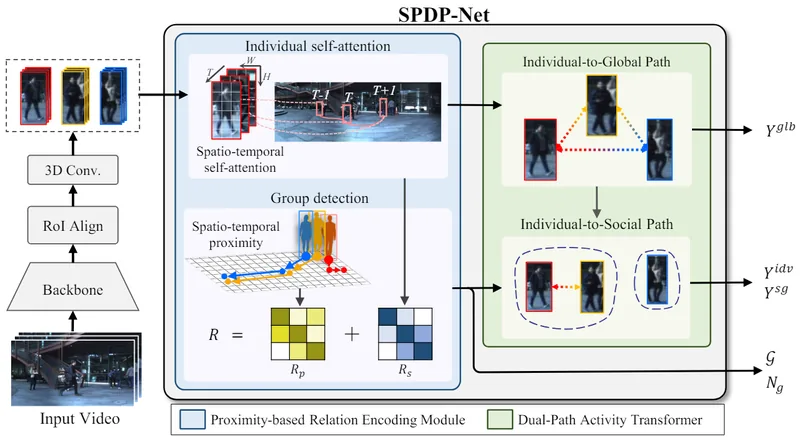
2023
-
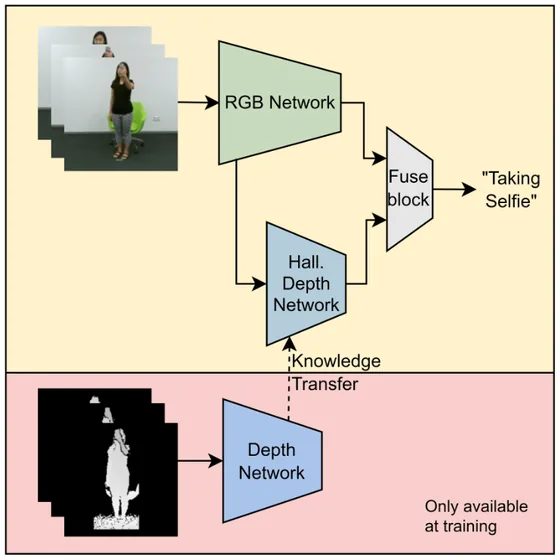
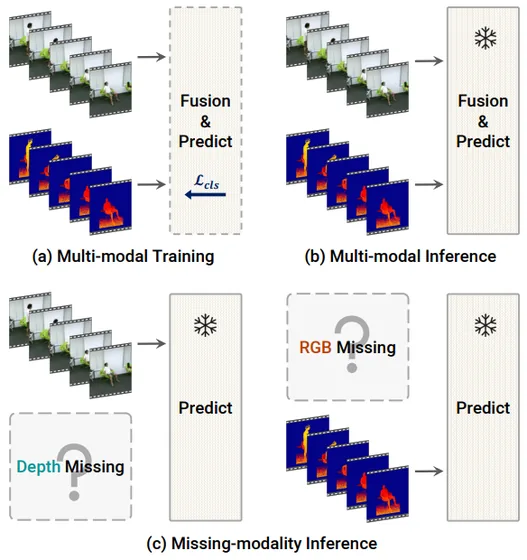
AHFu-Net: Align, Hallucinate, and Fuse Network for Missing Multimodal Action Recognition
VCIP 2023 Oral presentation
-
-
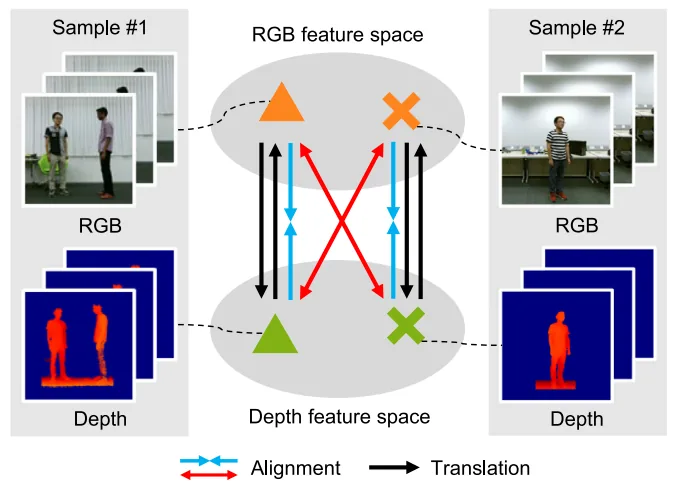
Cross-Modal Alignment and Translation for Missing Modality Action Recognition
CVIU 2023 IF 4.8
-
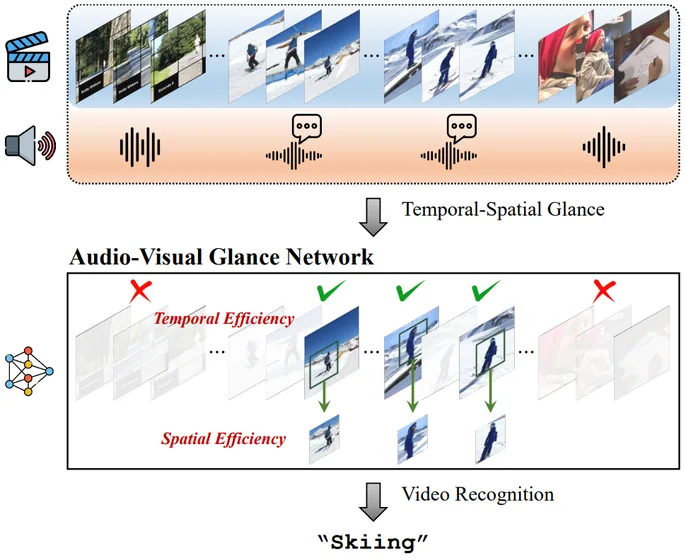
Audio-Visual Glance Network for Efficient Video Recognition
ICCV 2023 Invited Paper Talk @ CARAI Workshop
-
-
2022 & earlier
Academic Service
- Area Chair
- ACL ARR (Oct 2025)
- Conference Reviewer
- ICLR (2024–), NeurIPS (2024–), ICML (2025–), AAAI (2023–) CVPR (2024–), ICCV (2025–), ECCV (2024–) ACL ARR (Jan 2026–)
- Journal Reviewer
- TPAMI (2025–), TNNLS (2023–), TMLR (2025–), TIP (2025–)
Awards & Honors
- Jun 2025Outstanding Reviewer (711/12,593)IEEE Conference on Computer Vision and Pattern Recognition (CVPR)
- Dec 2024Finalist ($1,000)Qualcomm Innovation Fellowship 2024 Korea
- Oct 2023Invited Paper TalkCARAI Workshop, Center for Applied Research in Artificial Intelligence
- Dec 2022Finalist29th HumanTech Paper Award, Samsung Electronics Co., Ltd.
- Dec 2021Top Award ($10,000)LG Electronics Robot Contest, LG Electronics Co., Ltd.
- Nov 2019Excellence Award ($500)Creative Space G A.I&IoT Makerthon, GIST